build: 2026-10-19 20:32 UTC

Human Attention and Cognitive Load


Chapter 4 — Human Attention and Cognitive Load

The scarcest resource in software engineering — and how to measure it without surveillance.

Christopher J. Collins · Chapter Overview

Attention is the binding constraint

Compute can be provisioned. Repositories can be replicated. AI inference can be scaled.

Expert judgment, working memory, and sustained focus cannot.

  • A specialist can be employed full-time and still unavailable to a change

  • Calendar capacity is not uninterrupted capacity

  • A fatigued review is a review in name only

The goal is not to maximize visible activity — it is to maximize valuable outcomes per unit of scarce human attention, while preserving quality, learning, and sustainability.

Cognitive burden is multidimensional

Intrinsic

reasoning demanded by the problem itself

Representational

difficulty of how the system is expressed

Navigational

finding code, owners, tests, context

Coordination

tracking people, approvals, sequencing

Temporal

delays, interruptions, stale assumptions

Verification

proving the change is correct and safe

Tool interaction

IDEs, CI, review tools, AI assistants

Interventions act on different dimensions. One score erases the distinctions that make interventions possible.

A cognitive work model

Human cognitive work on an Engineering Change \(e\):

\[W_{human}(e) = W_{create} + W_{understand} + W_{verify} + W_{coordinate} + W_{recover} + W_{decide}\]
  • All six terms are latent — none observable directly at enterprise scale

  • Measurement becomes a problem of inference and validation, not counting

Measuring latent burden through proxies

Useful non-invasive signals include:

  • materially distinct files and concepts revisited

  • time from opening a review to first substantive action

  • repeated navigation through the same regions

  • review-response cycles and unresolved threads

  • simultaneously active Engineering Changes

  • repository and domain transitions

  • repeated CI runs without meaningful change

  • AI findings requiring independent investigation

No single proxy is a "cognitive-load score." Combine, control, and validate.

Context switching and attention residue
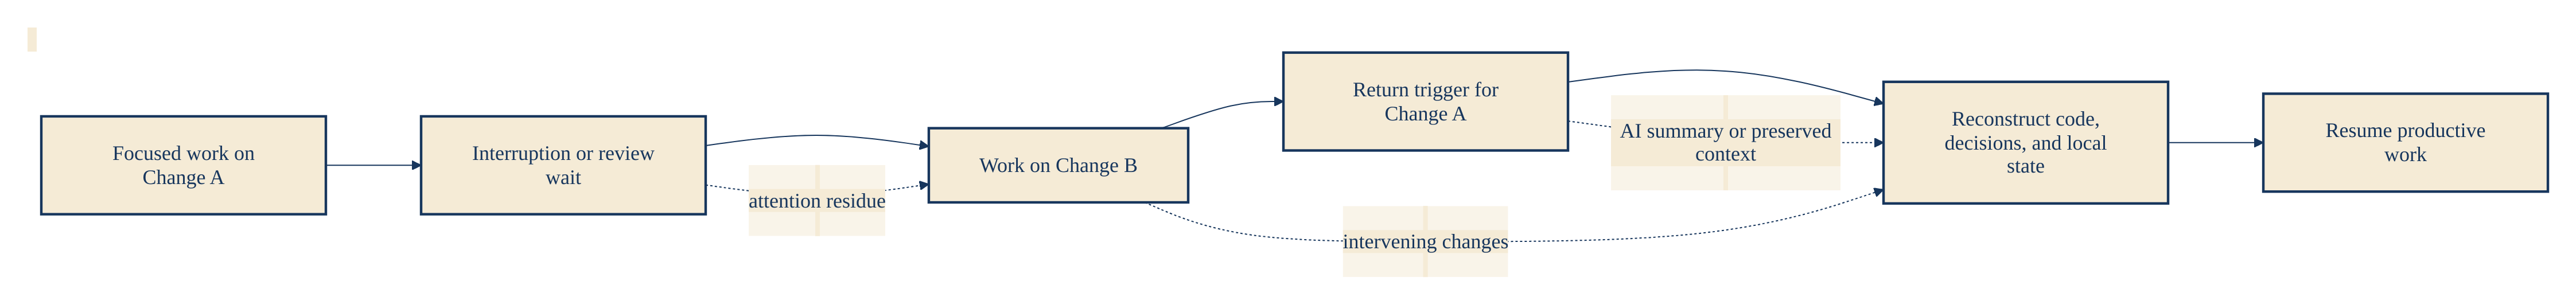
Context switching and recovery cycle

Recovery time model:

\[T_{recover}(p,e) = \alpha + \beta_1 \Delta t + \beta_2 N_{intervening} + \beta_3 C_e + \beta_4 D_e + \epsilon\]

The shaded region under the recovery curve is attention debt — cumulative work-below-steady-state imposed by the interruption.

Review is cognitive work, not elapsed time

Review is a sequence of operations:

  1. construct a mental model of intent

  2. identify changed behavior

  3. connect to architecture and domain constraints

  4. search for omissions and failure modes

  5. judge test evidence

  6. communicate findings actionably

  7. verify responses and revisions

A 1,000-line generated client may require less reasoning than a 5-line authorization change.

Comment counts are weak measures

More comments can mean: careful review, poor code, stylistic noise, misunderstanding, or high consequence.

Fewer comments can mean: excellent code, superficial review, high trust, or fatigue.

Comment data becomes useful only when enriched:

  • type · severity · novelty · action · resolution

  • human- or AI-originated · evidence supplied

  • eventual link to rework, defect, or incident

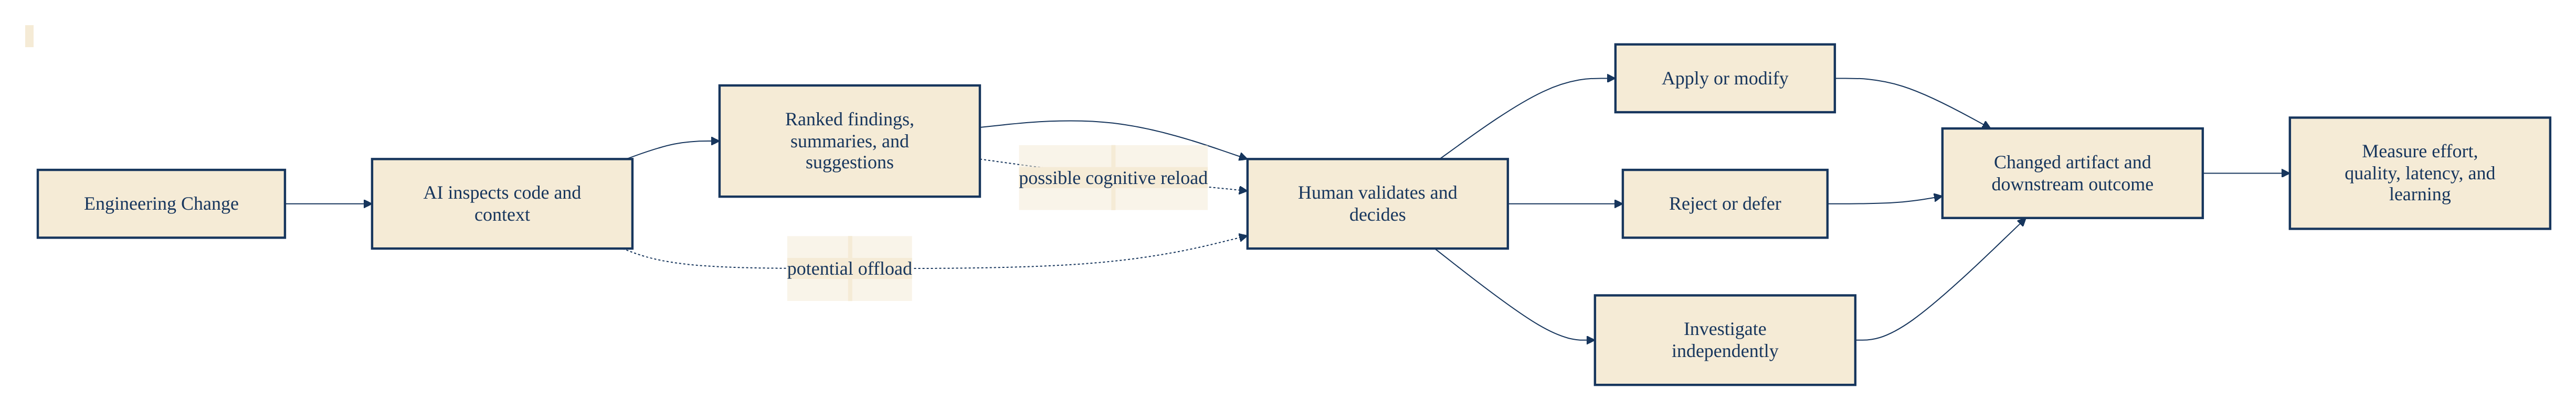
AI as a cognitive participant

Important

Cognitive offload — human work avoided because a reliable AI contribution performed or prepared it.

Cognitive reload — additional human work created by inspecting, correcting, rejecting, or recovering from AI output.

Net cognitive effect:

\[NCE(e) = W_{offload}(e) - W_{reload}(e)\]

Positive = net offload. Negative = the AI increased burden.

Why acceptance rate is insufficient

A suggestion may be accepted because it is trivial, auto-applicable, socially persuasive, or too hard to evaluate.

A valuable finding may be rejected because the author solved it differently.

Acceptance telemetry should be a distribution:

  • direct application · application with modification

  • independent equivalent fix · follow-up issue

  • acknowledgement without change · rejection with reason

  • no observable response · duplicate of human or AI finding

The Cognitive Offload Index

\[COI = \frac{\hat{W}_{human,control} - \hat{W}_{human,treatment}}{\hat{W}_{human,control}}\]

Quality-adjusted form:

\[QCOI = COI \times Q_r\]
  • \(COI = 0.15\) means estimated human work fell 15% vs. counterfactual

  • Never report without confidence intervals and guardrails

  • Never rank individuals or unrelated teams

Instrumenting AI review interactions

AI and human cognitive workflow

Minimum event stream: change IDs · model/prompt versions · context inspected · finding type/severity/evidence · human views and expansions · suggestion applications · comment replies · downstream edits · reviewer duplication · quality outcomes · cost and latency.

Interactions, not chain-of-thought.

Worked example: the $174k meeting cost

Eight engineers · 3.4 context switches/day · 11.5 min recovery · $145/hr loaded:

\[C_{recovery} = 3.4 \times \frac{11.5}{60} \times 145 \approx 94.5\ \text{USD/day}\]
  • Team: $756/day · ~$174k/year in pure recovery overhead

  • Consolidate two meetings → 2.1 switches/day, 10.8 min recovery

  • New cost: ~$100.8k/year — $73k saved

The economic argument becomes visible instead of anecdotal.

Ethical constraints are measurement requirements

Cognitive telemetry can easily become surveillance. Safeguards are non-negotiable:

  • collect the minimum data for the decision

  • prefer artifact and workflow events over keystrokes

  • aggregate by system, change class, or team

  • prohibit unsupported individual productivity scoring

  • document purpose, retention, access, downstream use

  • separate research telemetry from performance management

People who fear telemetry will alter behavior — and destroy the validity of the system.

Key takeaways

  • Human attention is the binding constraint in software delivery

  • Cognitive burden is multidimensional — preserve the components

  • Context switching creates recoverable, quantifiable cost

  • Review burden depends on semantics and architecture, not size

  • AI creates both offload and reload — measure the net

  • Acceptance rate alone does not measure AI value

  • Proxies require predictive, convergent, discriminant, and experimental validation

  • Trust and ethics are prerequisites for valid measurement

Next

Chapter 5 — AI as a First-Class Engineering Participant

Provenance · agency · accountability · measuring the AI collaborator itself.