Chapter 12 — Experiment Playbooks
Christopher J. Collins
Chapter 12 — Experiment Playbooks
Turning measurement and causal methods into reusable, decision-driven experiments.
Christopher J. Collins · Chapter Overview
From methods to playbooks
Previous chapters described how to measure and estimate. This chapter turns those methods into reusable experiment playbooks.
Each playbook forces the owner to make assumptions explicit — before results arrive.
A playbook is a structured starting point, not a fixed recipe.
Anatomy of a playbook
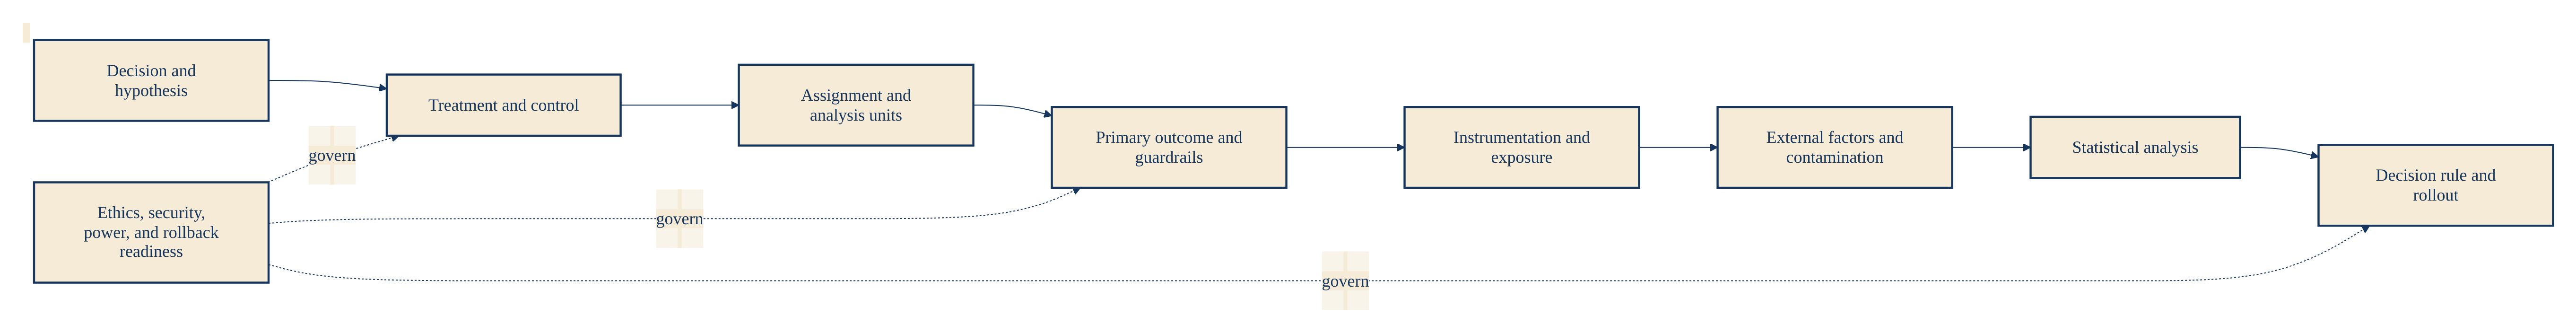
Every playbook names: decision · hypothesis · treatment · control · assignment unit · analysis unit · eligibility · primary outcome · guardrails · exposure · external factors · statistical design · minimum practical effect · stopping rules · interpretation risks.
Playbook 1 — AI pull-request reviewer
Decision: Adopt, replace, or expand an AI reviewer?
Treatment — a precisely versioned model, prompt, index, severity policy, ranking policy, and UI
Assignment — Engineering Change or repository cluster (reviewers and code are shared)
Primary outcome —
Guardrails: severe escapes · rollback · security · cognitive reload · trust calibration.
Playbook 3 — Merge queue introduction
Decision: Should this repo/portfolio adopt a merge queue?
Mechanism — fewer broken-main events and redundant CI; more queueing latency, less author control
Assignment — repository cluster or switchback by time block; never individual (shared infrastructure)
Primary outcome — quality-adjusted time from approval to integrated mainline
Guardrails: failed mainline builds · queue age · urgent-change latency · CI cost · author context recovery.
Playbook 4 — CI acceleration
Decision: Does faster CI create enough engineering value to justify infrastructure cost?
Interpretation risk: Reducing job duration may not reduce Engineering Change lead time if review or deployment is the true constraint.
Playbook 6 — Pull-request size guidance
Decision: Does encouraging smaller pull requests improve flow and review quality?
Unit of analysis — Engineering Change, not individual pull request
Otherwise one intent split into ten PRs looks artificially productive
Estimate heterogeneous effects by topology, coupling, familiarity, complexity
Do not adopt a universal line-count threshold. Find ranges and contexts where smaller slices improve total outcomes.
Playbook 7 — Repository consolidation
Decision: Would consolidation reduce coordination and build friction enough to justify migration cost and new coupling?
Randomization rarely feasible
Use matched comparison groups, synthetic controls, interrupted time series
Record reorganizations and platform migrations — they will confound
Guardrails: build-system complexity · access control · blast radius · team autonomy · migration disruption.
Playbook 10 — Autonomous maintenance agent
Decision: Can an agent safely complete bounded maintenance tasks with less human effort?
Eligible: dependency upgrades, mechanical migrations, formatting, test generation — deterministic validation, easy rollback.
Primary outcome: accepted tasks per unit of quality-adjusted human attention.
Attribution must include: full agent runtime, human supervision, corrections, downstream rework.
Common failure modes
Wrong unit — PR metrics for Engineering-Change-level effects
Multiple mechanisms — new model + prompt + UI + policy shipped together
Missing exposure — assignment recorded, actual use unknown
Short window — speed measured; quality and learning still to arrive
Ignoring subgroups — positive average hides harm to novices or high-risk repos
No decision threshold — significance without practical significance
External-factor control checklist
For every playbook, record:
release and planning cycles | reorganizations |
holidays and staffing | new tools or model releases |
incidents and outages | repository migrations |
policy and compliance | vendor or platform failures |
Scope factors to affected entities and time windows — not global notes.
Pre-experiment readiness
Do not launch until:
treatment and control are technically stable
assignment and exposure are instrumented
primary outcomes and guardrails are available
baseline variance and power are understood
security, legal, and ethical reviews are complete
stopping and rollback rules are defined
concurrent interventions are registered
The cost of a delayed launch is almost always smaller than the cost of a study that has to be redone.
Worked example: AI-review playbook
180 backend teams. Vendor V, model M @ 2024-08, prompt P rev 12. Assign by team; analyze by Engineering Change. Stratified by baseline latency and language.
Baseline \(\sigma = 42\) minutes per change; MDE = 8%.
Result: −6.4% effort (CI 2.1%–10.7%); escapes unchanged. Below the pre-declared 8% MDE. Real but too small — re-run in six months after model refresh.
Post-experiment decision record
Every experiment should leave a durable record:
estimated causal effects and intervals
practical significance vs. pre-declared threshold
guardrail status
heterogeneous effects
external-factor sensitivity
economic interpretation and limitations
adopt · revise · reject · extend
rollout and monitoring plan
The output of a good experiment is organizational knowledge — even when the intervention fails.
Key takeaways
Playbooks make mechanisms, assumptions, and decision rules explicit
The Engineering Change is usually the correct analysis unit
Primary outcomes should represent quality-adjusted system value
Exposure, external factors, guardrails, and heterogeneous effects are not optional
Every experiment ends with a durable decision and learning record
Next
Chapter 13 — Portfolio Decisions
From individual experiments to allocating scarce engineering capacity across competing initiatives.