The Science of Engineering Intelligence
Christopher J. Collins
Chapter 16 — The Science of Engineering Intelligence
From dashboards to a cumulative empirical discipline: constructs, evidence, replication, and the shared infrastructure of a real science.
Christopher J. Collins · Chapter Overview
From analytics to discipline
Engineering analytics is local and ephemeral. A dashboard answers a question; nobody can reproduce it a year later.
A scientific discipline requires:
explicit constructs and observable units
falsifiable hypotheses
reliable, validated measurement
transparent uncertainty
reproducible methods
cumulative evidence
mechanisms for correction
Engineering Intelligence should aspire to these properties — not imitate physics.
The object of study
The primary object is not the individual engineer.
Important | It is the production and operation of Engineering Changes within an organizational system. |
A change connects intent, humans and machines, artifacts, review, deployment, production consequences, and economic value — analyzable across tools without equating activity with performance.
Levels of explanation
A useful theory names the level it operates at — and how it connects to the others.
Artifact | code, tests, configuration, models, schemas |
Change | design → implement → review → deploy → observe |
Queue | competition for reviewers, CI, environments |
Team | coordination, expertise, ownership, interruption |
Architecture | dependencies, coupling, blast radius |
Portfolio | capacity allocation across products and risk |
Enterprise | capital, governance, talent, vendor strategy |
Constructs vs. observables
Many important engineering concepts cannot be observed directly:
cognitive load
change complexity
review quality
coordination cost
architectural risk
developer experience
organizational learning
engineering value
These are constructs. They require indicators — and the indicators require validation. No single signal should be treated as the construct itself.
The theory-to-evidence chain
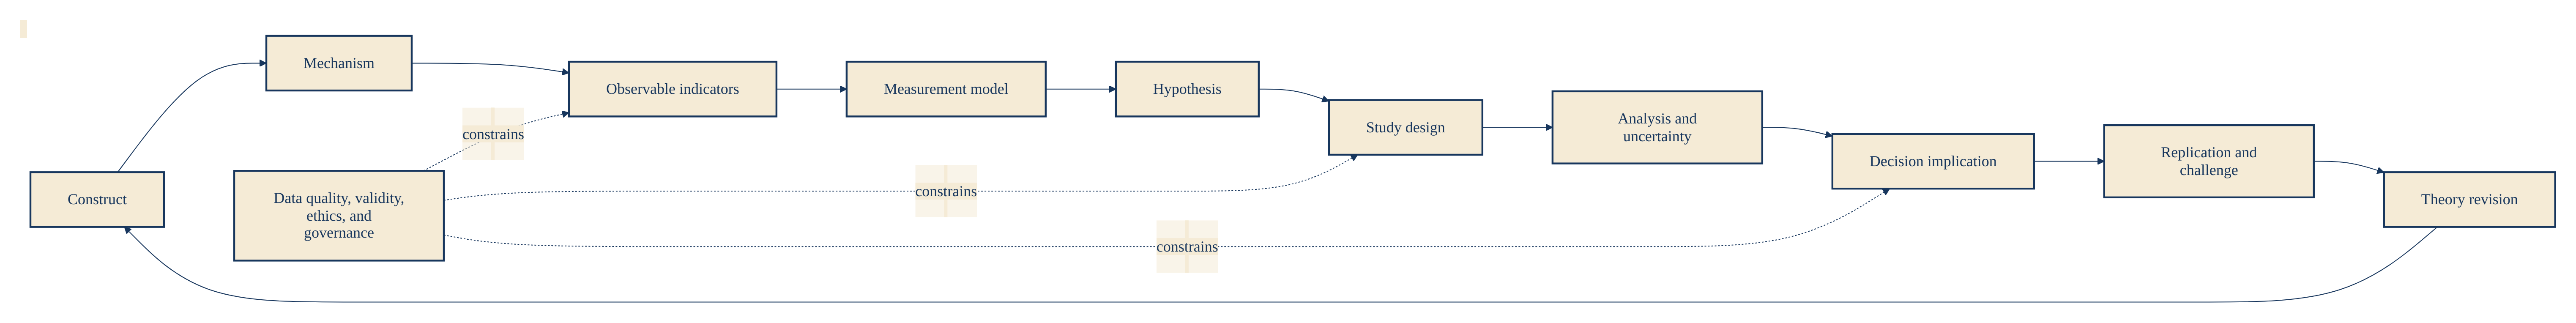
Every claim should be traceable: construct → mechanism → indicator → measurement → hypothesis → design → analysis → decision → replication.
This discourages the drift from convenient telemetry field to metric to target to unsupported performance claim.
Falsifiable hypotheses
"AI code review improves engineering productivity."
Not falsifiable.
"For eligible medium-risk PRs, the AI reviewer will reduce median human review effort by at least 15% without increasing escaped sev-1/2 defects, controlling for repository and change complexity."
Defines population, treatment, effect, outcome, guardrail, comparison, adjustment. Falsifiability forces clarity before data is examined.
Four claim types
Claims must be labeled — and priced — by type.
Type | Question | Example |
Descriptive | What happened? | Review wait time rose this quarter |
Predictive | What is likely to happen? | This change likely needs rollback |
Causal | What would change under intervention? | Merge queue reduced integration failures |
Prescriptive | What action, given objectives and cost? | Route to security specialist; hold deploy |
Correlation is not intervention effect. Prediction is not prescription.
Measurement validity
A metric can be computed correctly and still be scientifically invalid.
Construct — does it represent the intended concept?
Content — does it cover the concept’s dimensions?
Criterion — does it agree with a credible reference?
Convergent — do sibling measures move together?
Discriminant — can it distinguish related concepts?
Ecological — does it survive real engineering conditions?
Reliability, invariance across groups, and calibration of probability scores complete the picture.
Ground truth is constructed
Defect labels depend on detection, linkage, severity assignment, rollback interpretation, reviewer awareness, and near-miss recording.
There is no unlabeled defect ground truth waiting to be harvested.
Annotation is itself a measurement process: ontology, inclusion rules, blinding, calibration, disagreement resolution, drift review. For hard judgments, preserve annotator distributions — don’t collapse disagreement into a single label.
Benchmarks and ranking
Benchmarks can accelerate progress — or distort it.
A useful benchmark specifies task, representative populations, temporal splits, repository separation, leakage controls, uncertainty, cost-sensitivity, subgroup reporting, and a protected holdout.
Ranking systems live or die on operational measures:
precision / recall at \(k\)
MRR, NDCG, average precision
expected utility at review budget
severe-finding recall, time-to-first-actionable
A system that finds the right issue but buries it under twenty low-value comments is correct and useless.
Replication, pre-registration, negative results
Internal replication tests whether a finding is local, seasonal, or robust enough for enterprise decisions. External replication is the price of a cumulative field.
A publishable study ships a reproducibility package: plan, metric versions, schemas, code, data-quality report, sample logic, models, robustness checks, synthetic fixtures, decision record.
Pre-registration doesn’t prevent exploration. It distinguishes confirmatory evidence from discoveries made after inspecting the data.
Engineering orgs routinely suppress tools that didn’t help, interventions that helped only one workflow, models that failed under load, effects that vanished after adjustment. A mature discipline records these.
Natural experiments and adaptation
Engineering orgs continuously produce quasi-experimental variation: phased rollouts, policy thresholds, outages, migrations, vendor changes.
With explicit assumptions: diff-in-diff, regression discontinuity, interrupted time series, IV.
An intervention effect is not permanently fixed. People learn the metric. Teams alter the workflow. Distributions shift.
Engineering Intelligence requires continuous revalidation and explicit study of adaptation.
Evidence maturity levels
Attach a level to every consequential claim.
L0 | Anecdote — plausible, unmeasured |
L1 | Descriptive evidence — measured pattern, documented definitions |
L2 | Replicated association — across populations, with adjustment |
L3 | Credible causal evidence — randomized or defensible quasi-experiment |
L4 | Replicated causal mechanism — with known boundary conditions |
L5 | Operationally validated policy — governed, durable net benefit |
The maturity level accompanies the recommendation.
Shared infrastructure and evidence graph
A cumulative discipline needs shared infrastructure:
canonical event contracts and Change schemas
metric registries, benchmark tasks, synthetic generators
experiment templates and analysis libraries
privacy-preserving collaboration — federated, differential privacy, synthetic, enclaves
replication registries and evidence maps
Studies become an open evidence graph linking constructs, metrics, datasets, interventions, mechanisms, findings, replications, contradictions, decisions — so leaders see provenance, not just the latest headline.
Anti-patterns
Dashboard empiricism — a visible pattern treated as explanation
Metric essentialism — the proxy taken for the construct
One-company universalism — a local result reported as a law
Benchmark overfitting — public test won, operational value lost
Causal language without causal design
Hidden researcher degrees of freedom
Publication of winners only
Permanent validity — a metric assumed to survive system adaptation
Key takeaways
Engineering Intelligence should mature into a cumulative empirical discipline
The Engineering Change is the primary unit of study
Separate constructs from observables; validate both
Distinguish descriptive, predictive, causal, prescriptive claims
Reproducibility, replication, negative results, transportability are non-negotiable
Benchmarks must reflect operational utility, uncertainty, and cost
Systems adapt — findings require continuous revalidation
Shared schemas and privacy-preserving collaboration can build an evidence base larger than any one organization
Next
Chapter 17 — The Future of Engineering Intelligence
Where the discipline goes next: autonomous participants, evolving architectures, and the enterprise systems that will need to keep up.