Reconstructing an Engineering Change
Workshop — 90 minutes
Reconstructing an Engineering Change
A hands-on workshop derived from Chapter 3 of Engineering Intelligence.
90 minutes · 4 hands-on segments
Learning outcomes
After this workshop you can:
Draw the boundary of one Engineering Change from a messy artifact pile
Enumerate linking signals between artifacts and assign a defensible confidence
Sketch a change graph — intents, PRs, deploys, approvals — annotated with provenance
Attribute cost, latency, and blast radius to a reconstructed change instead of to individual PRs
Name the failure modes your own reconstruction is most exposed to
The problem
Friday afternoon. A payments incident.
Leadership asks: "What change caused this, what did it cost us to build, and who’s on point for the fix?"
Your evidence: 4 pull requests across 2 repos, 3 tickets (one closed as duplicate), a feature flag, two deployments six hours apart, and a Slack thread nobody remembers.
What is the "unit of change" you’re going to attribute this to?
Try to answer with PRs alone. Notice what falls off the table.
Why the pull request isn’t the unit
A customer capability may span web, mobile, API, shared library, migration, flag, deploy, docs, verification. Each in a different system.
The reverse: one PR often bundles refactor + dependency bump + feature — three unrelated intents in one artifact.
Repository conventions decide the boundary — not engineering intent.
Measurement must separate observable artifacts from the logical change they realise.
The Engineering Change, formally
An Engineering Change is the temporally bounded set of activities that transform one coherent intent into one or more accepted outcomes.
Intent \(I\) · Artifacts and activities \(A\) · Relationships \(R\) · Outcomes \(O\) · Time \(\tau\) · Provenance \(\Pi\).
The last one — provenance — is what makes the graph auditable.
The artefact pack
Each pair receives a printed pack:
4 pull requests across 2 repositories (titles, authors, timestamps, files touched, references)
3 tickets — one open, one closed-fixed, one closed-as-duplicate
2 deployment records with build IDs
1 feature-flag configuration change
1 incident record from four days later
1 design doc fragment
None of them carry an Engineering-Change: trailer. Welcome to your existing estate.
Segment 1 (15 min) — draw the boundary
Pair up. Read the pack.
On paper, list which artefacts you believe belong to the same Engineering Change and which do not. Circle the boundary. Put question marks on the ones you’re unsure about.
Do not draw edges yet. Just membership.
Report back: one artefact your pair fought about, and the argument that changed one of your minds.
What did you actually use?
You just used signals — even if you didn’t name them.
Shared ticket ID or explicit reference
Overlapping authors or reviewers
Temporal proximity
Shared files, packages, or services
Coordinated deployments
Shared feature-flag names
Semantic similarity of titles and descriptions
Every one of these is inferential. None is ground truth.
Signals aren’t equal
| Signal | Typical weight | Fails when… |
|---|---|---|
Explicit change-ID trailer | 1.00 | Rarely — this is declared linkage |
Ticket reference in PR body | high | Ticket stale, reused, or copied across unrelated work |
Shared author + tight window | medium | Active engineers straddle many changes |
Coordinated deploy window | medium | Release train batches unrelated intents |
Semantic title similarity | low | Template titles ("bump deps", "fix flake") |
Same feature flag | high | Flag reused for a follow-up epic |
Confidence, as a first-class attribute
Every membership decision carries a number.
| Class | Range | Use it for… |
|---|---|---|
Declared | 1.00 | Executive attribution, financial reporting |
Strongly inferred | 0.90–0.99 | Governed metrics, cost accounting |
Inferred | 0.70–0.89 | Team dashboards, flow analytics |
Tentative | 0.50–0.69 | Exploration only |
Rejected | below | Not in the graph |
The threshold depends on which decision the number will support.
Segment 2 (20 min) — score the signals
Back in your pair. For each artefact you provisionally included in Segment 1:
List every signal that links it to the intent
Assign each signal a weight (your own — argue about it)
Multiply or combine to a membership confidence in [0,1]
Classify it: declared / strongly inferred / inferred / tentative / rejected
Re-examine your boundary. Do any artefacts fall below your threshold?
Report back: one artefact you demoted after scoring, and the signal you had over-trusted.
From membership to graph
Membership tells you which artefacts belong. The graph tells you how they relate.
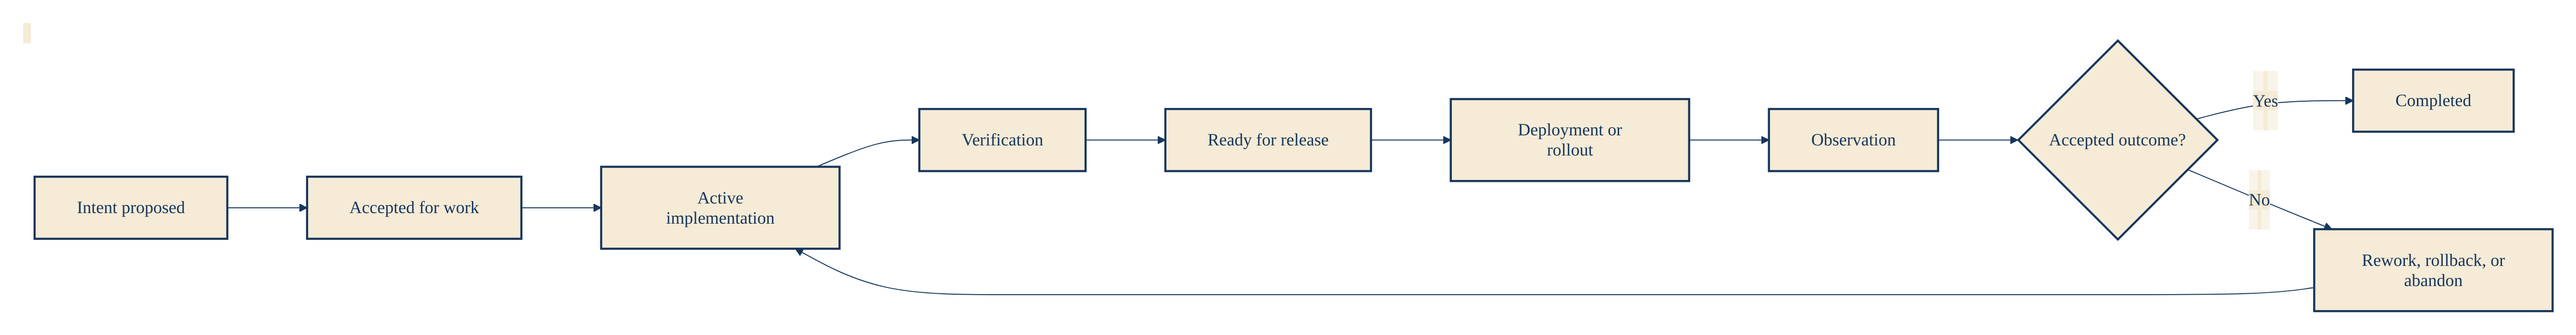
Edges — IMPLEMENTS, DEPENDS_ON, REVIEWS, DEPLOYS, VERIFIES, ROLLS_BACK, CAUSED_BY — carry time, source, and confidence just like nodes.
Provenance rides every edge
An edge answers "why are these linked?" — not just that they are.
{
  "artifact": "repo-a#1842",
  "engineeringChange": "EC-01J8...",
  "confidence": 0.96,
  "evidence": [
    {"type": "ticket_match", "value": "PAY-431", "weight": 0.52},
    {"type": "explicit_pr_reference", "value": "repo-b#991", "weight": 0.27},
    {"type": "coordinated_deployment", "windowMinutes": 18, "weight": 0.11}
  ],
  "modelVersion": "reconstruct-v3.4"
}
Silent mutation destroys trust. Every link must be reversible with an explanation.
Segment 3 (20 min) — draw the change graph
Take a fresh sheet.
Put the intent at the top (one node — the coherent purpose)
Add each accepted artefact as a node
Draw typed edges between them:
IMPLEMENTS,REVIEWS,DEPLOYS,VERIFIESOn each edge, annotate: source of the link, signal(s) used, confidence
Mark the outcome node — accepted, partial, rolled back, abandoned
Do not skip the annotation. That is the exercise.
Report back: the edge with the lowest confidence on your graph, and what would raise it.
The graph unlocks questions PRs can’t
Which artefact lies on the critical path?
How many repo and ownership boundaries were crossed?
Which approvals delayed acceptance?
Did the incident originate from a change spanning several repositories?
How much human and AI effort accumulated across the whole change?
Each is a graph traversal, not a flat-table query.
Critical path and blast radius
Path duration through the DAG of your change:
Latency = time along the critical path from intent to accepted outcome
Cost = effort accumulated across all artefacts and reviews, weighted by confidence
Blast radius = services, teams, and users affected by the outcome (or by its rollback)
Attributing any of these to a single PR under-counts, over-counts, or attributes to the wrong owner.
Weighted cost, honestly
For your reconstructed change, effort splits by evidence class:
Report a floor (deterministic only), an expected (confidence-weighted), and a ceiling (all evidence unweighted). Do not collapse them to one number on an exec slide.
Analogy from Chapter 3’s worked example: 20.3h floor, 24.1h expected, 26.4h ceiling — all three ship together, all three stamped reconstruct-v3.4.
Segment 4 (15 min) — attribute the incident
Return to the incident record in your pack. It surfaced four days after the second deployment.
Using only the graph you drew:
Which artefact(s) are the most plausible cause? What’s your confidence?
Which owners would you page? What’s the smallest set?
What is the blast radius — services, users, downstream changes?
If you had to report a cost of the change so far to your CFO, what floor / expected / ceiling would you cite?
Report back: the attribution decision your pair is least confident about, and what evidence would move it.
Failure modes you just felt
Ticket links as ground truth — one of your tickets was closed-as-duplicate. Did you trust it?
Clustering by author + time — did an active engineer create a false join?
Ignoring deployment evidence — flow truncates at merge; your incident lived downstream
Displaying inferred links as facts — did any 0.7 edge sneak onto the exec slide?
One giant initiative node — did you resist the temptation to lump?
Recomputing without versioning — every number needs a model version stamp
What to take home
You now have a reconstructed change graph for one real intent
You have floor / expected / ceiling effort numbers, each with provenance
You have a list of signals your organisation has — and the ones it lacks
You have a confidence threshold you can defend for the next decision class up
The next step in your own estate is to instrument a change ID and earn declared-linkage confidence for new work — while keeping probabilistic reconstruction for the backlog.
Reading and running
Read: Chapter 3 of Engineering Intelligence
Run:
companion/notebooks/08-engineering-change-reconstruction.py— the reference implementation of the worked exampleNext: Chapter 4 — attributing the cost you just estimated, honestly
Close
Pull requests are what your tools happen to record.
The Engineering Change is what your organisation was actually trying to do.
Reconstruct the second one — with confidence, provenance, and a version stamp — and the rest of the book has something to measure.